Software development
A fit for agents that inspect a repository, implement a change, and iterate through test feedback.
Built for agents that get work done. Explore faster execution, stronger coding, and a lower cost per task.
*MiniMax-reported reduction versus its predecessor for agentic tasks. Benchmark scores and speed figures are provider-reported.
Choose a model around the work your agent needs to finish.
A fit for agents that inspect a repository, implement a change, and iterate through test feedback.
Bring planning and tool calls into workflows that span documents, files, and business systems.
Explore desktop automation and security tasks with a model evaluated on real environment interaction.
Explore the official results across software engineering, business automation, computer use, and cybersecurity.
MiniMax-reported evaluations. Compare results within the same benchmark and test the model on your own workload.
| Benchmark | Category | MiniMax M3.1 Flash | DeepSeek V4.1 Flash-1017 | DeepSeek V4.1 Flash | Kimi K3 | GLM 5.3 | GPT-5.6 Sol | Opus 5 |
|---|---|---|---|---|---|---|---|---|
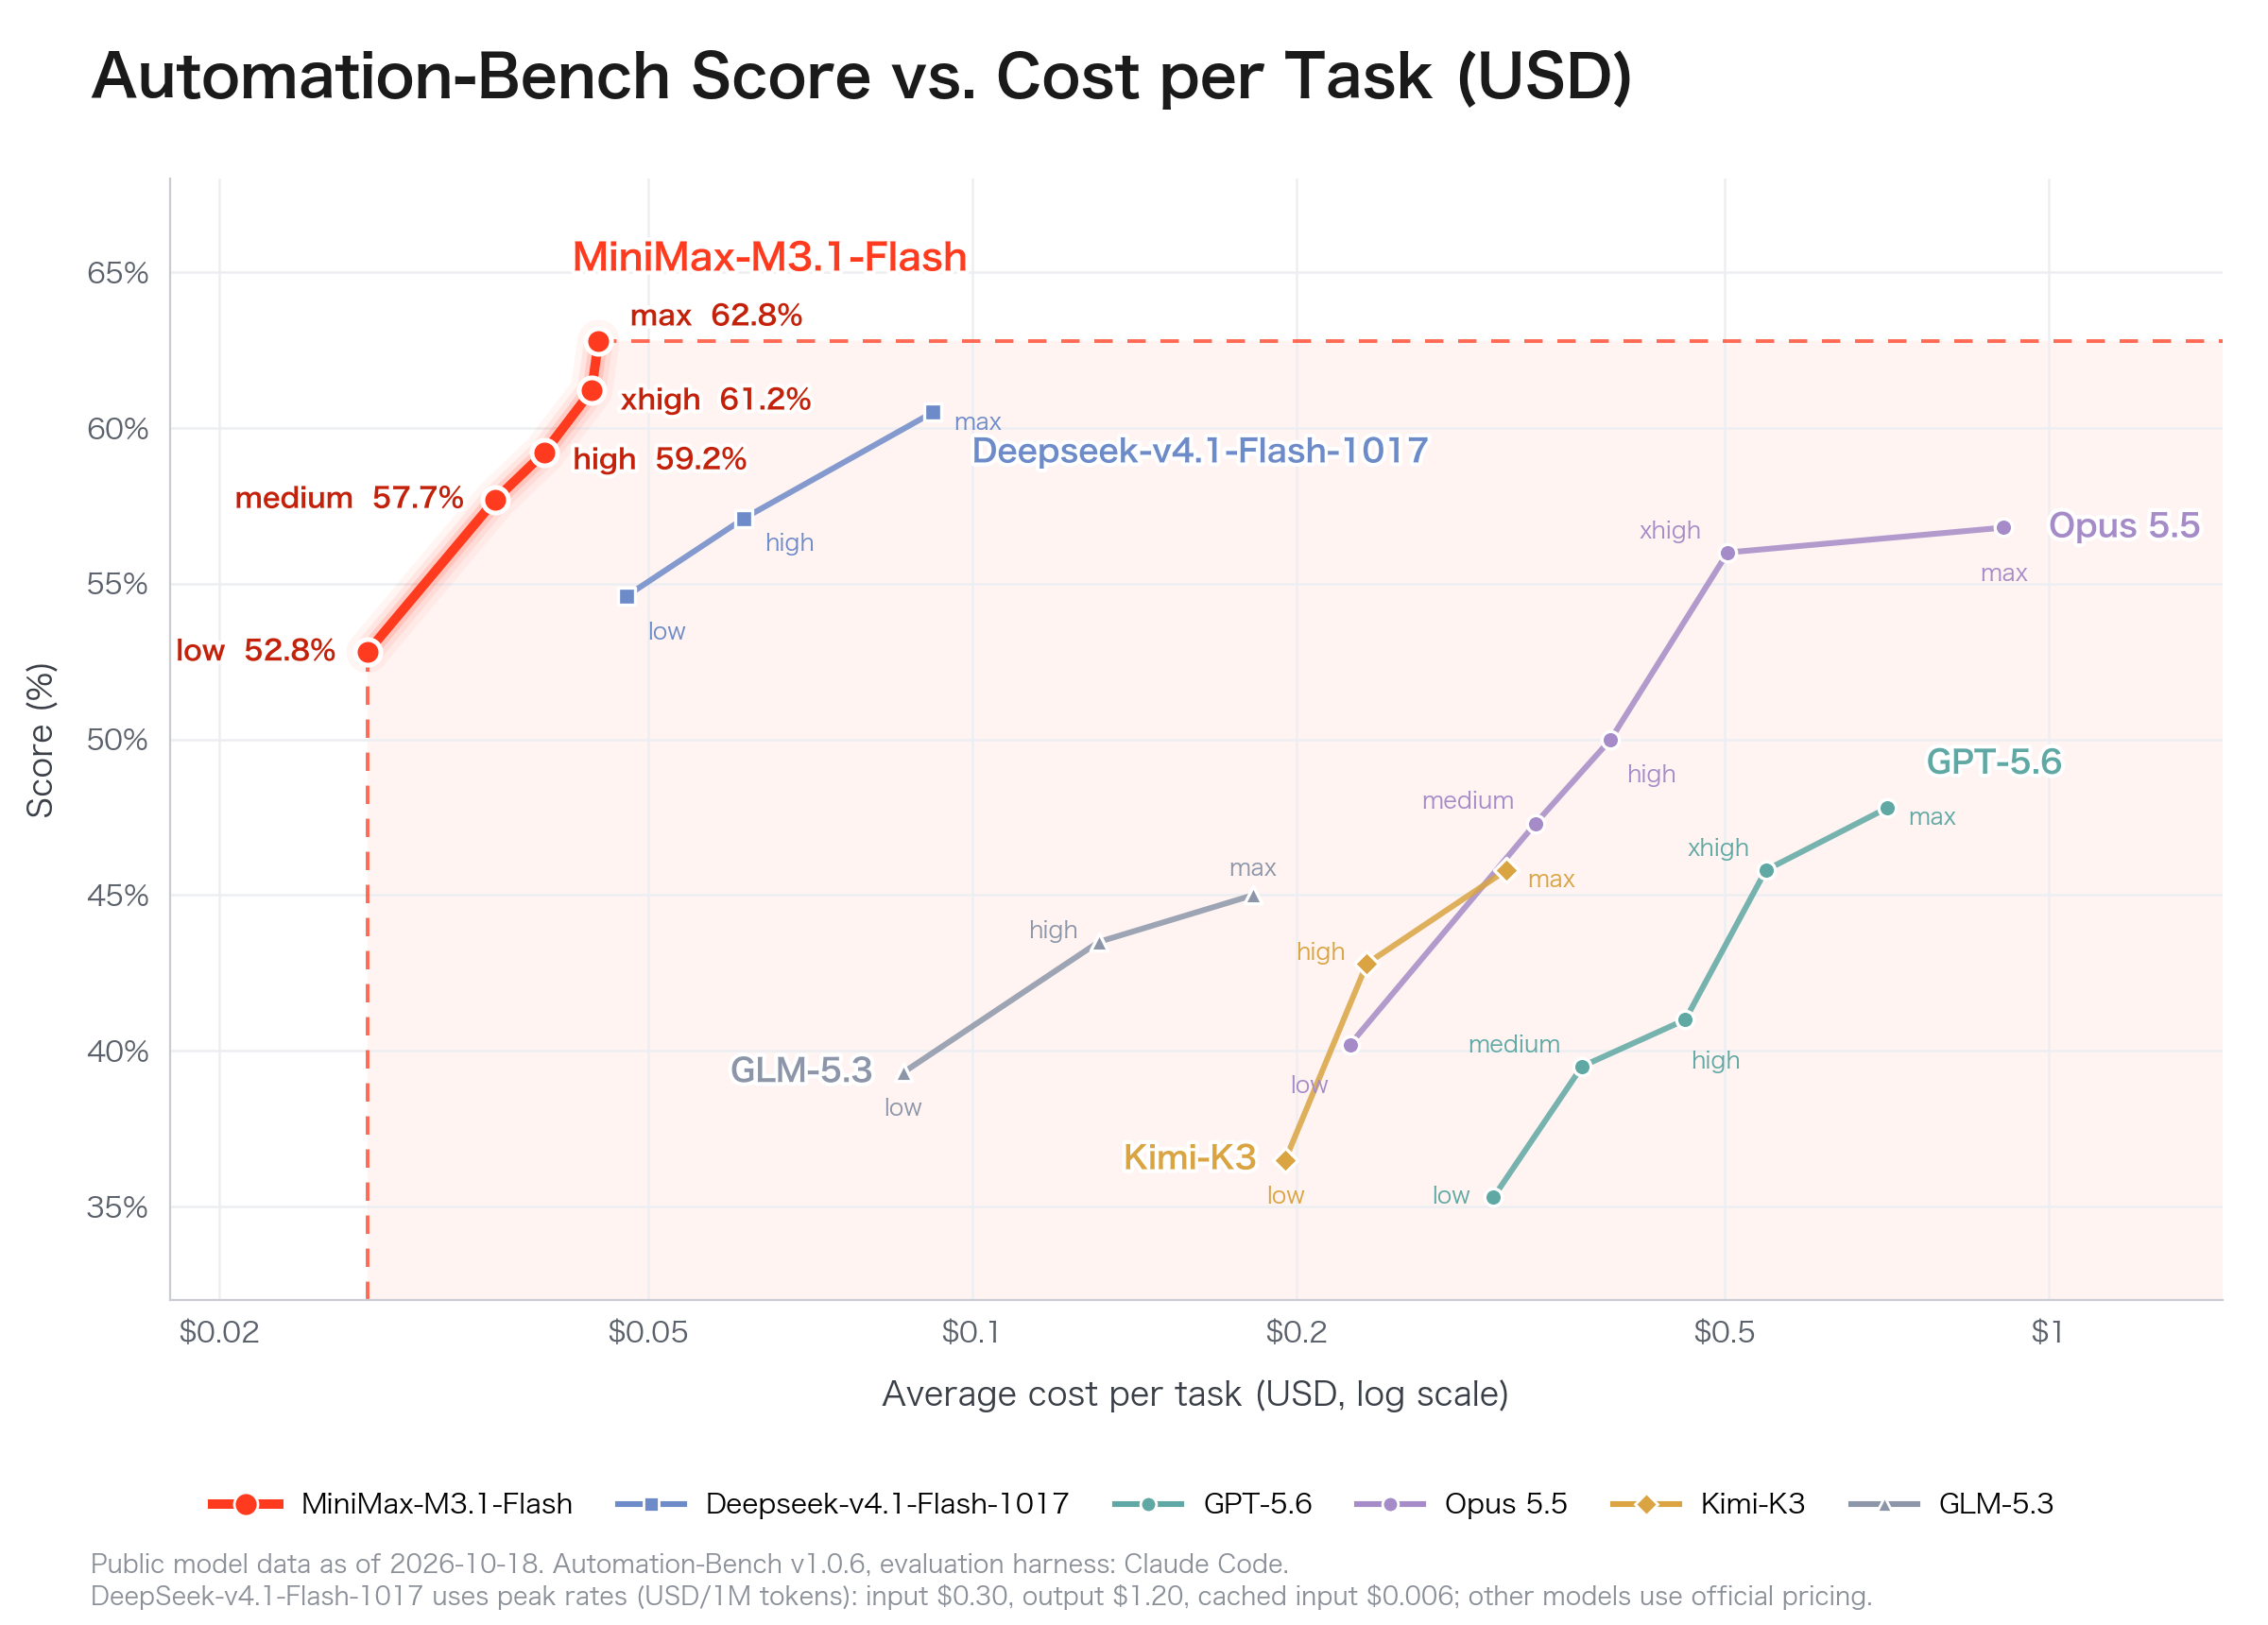
| Automation-Bench v1.0.6 | CoWork | 62.8 | 60.5 | 54.8 | 46.7 | 48.8 | 45.8 | 50.3 |
| BankerToolBench | 76.2 | — | 73.7 | 69.1 | 74.5 | 74.6 | 76.2 | |
| GDP.pdf AA | 20.8 | — | 12.8 | 22.0 | 11.2 | 27.2 | 21.6 | |
| Terminal Bench 4.0 | 38.1 | 42.3 | 31.2 | 12.6 | 37.9 | 39.9 | 51.8 | |
| LOCA-Bench 256K | 60.3 | — | — | 49.7 | 50.3 | 60.0 | 53.7 | |
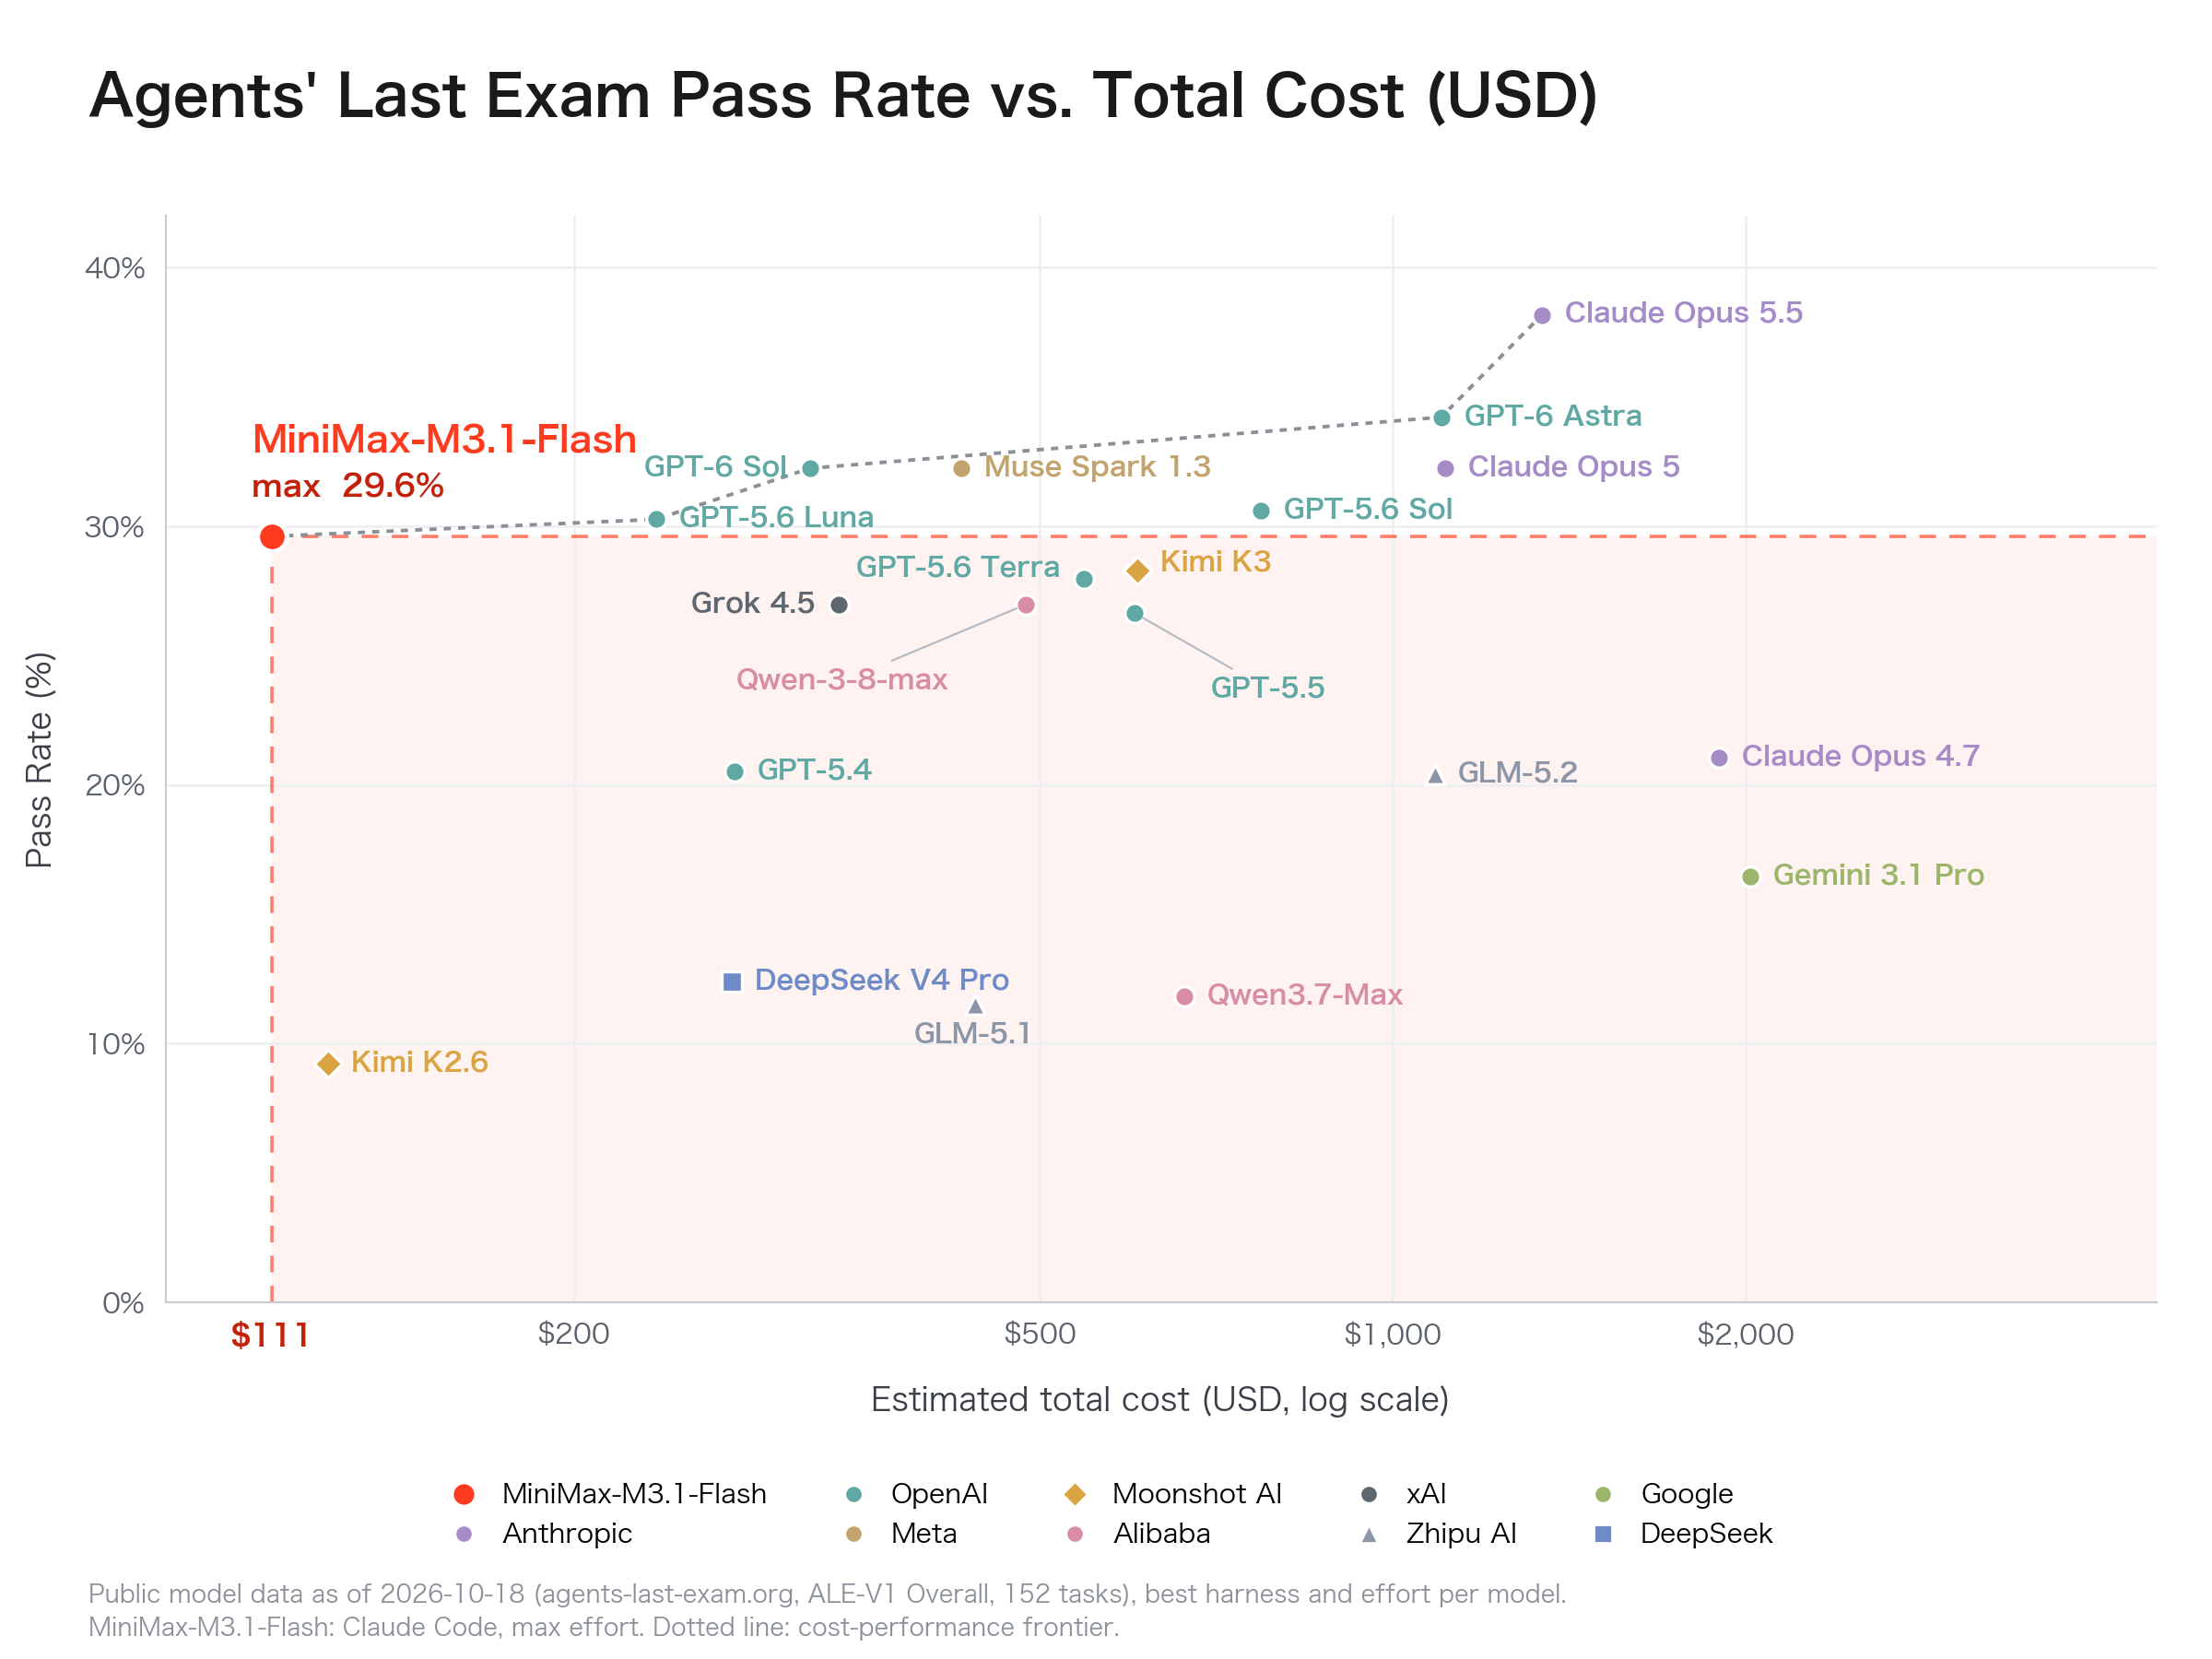
| Agents’ Last Exam | Computer Use | 29.6 | — | — | 28.3 | — | 30.6 | 32.2 |
| OSWorld 2.0 | 61.7 | — | 54.3 | 58.3 | — | 65.7 | 70.6 | |
| PostTrain Bench v1.1 | Coding | 39.3 | — | 30.5 | 36.6 | 37.5 | 36.2 | 40.4 |
| DeepSWE v1.1 | 73.7 | 77.0 | 74.2 | 67.5 | 66.9 | 73.0 | 74.0 | |
| NL2Repo-Bench | 61.2 | 68.2 | 65.4 | 58.0 | 58.0 | 56.8 | 75.3 | |
| SWE Refactor Bench | 23.0 | — | 11.8 | 19.5 | 10.4 | 28.5 | 31.0 | |
| CyberGym | Cyber | 82.2 | — | — | 80.0 | 84.5 | 83.6 | — |
| BabyVision (w/tools) | General Capabilities | 91.0 | 92.5 | 89.6 | 85.7 | — | 89.9 | 94.1 |
| HLE (w/o tools) | 43.4 | 44.0 | 39.2 | 43.5 | 42.3 | 49.5 | 55.6 | |
| CharXiv RQ | 82.5 | — | 69.0 | 84.8 | — | 85.2 | 83.7 |
Source:MiniMax official announcement ↗· October 19, 2026. Bold values indicate the highest published score in each row. — means no score was reported, not zero. Evaluation setups vary; see the source for methodology.
MiniMax reports nearly three times faster online inference and 70% lower agentic usage cost than its predecessor. Flash is built for workflows where repeated model and tool calls add up.
What the chart showsOn Automation-Bench, Flash reaches a 62.8% score at a lower plotted cost per task than the other models shown.
$0.15 input · $0.60 output · $0.015 cached input
Provider API pricing; separate from MyClaw billing.
Evaluate Flash on implementation tasks, cross-application actions, and workflows that depend on sustained tool use. The official release covers both coding and computer-operation benchmarks.
What the chart showsOn Agents’ Last Exam, Flash reaches a 29.6% pass rate at an estimated $111 total cost in MiniMax’s evaluation. Some models score higher at a higher plotted cost.
Two different starting points for your next agent workflow.
| Model comparison | M3.1 Flash | M3 |
|---|---|---|
| Focus | Efficient agent execution and lower task cost | Long-context coding and multimodal workflows |
| Speed | 200+ TPS output; 170+ TPS median, per MiniMax | The reference model page does not give a comparable speed figure |
| Context window | Not specified in the launch article | Up to 1M tokens, per the M3 model page |
| Evaluation highlights | DeepSWE v1.1, OSWorld V2, CyberGym | SWE-Bench Pro and long-horizon agent execution |
| Best first test | Repeated tool calls, automation, and cost-sensitive coding | Large repositories, long documents, and multimodal context |
Different benchmarks are not directly comparable. Sources:M3.1 Flash announcement ↗andMyClaw M3 model page ↗.
Inspect code, implement features, and iterate through test feedback in software development workflows.
Move from a business task to a structured plan and tool actions across documents, files, and connected systems.
Navigate interfaces and complete multi-step tasks across applications with an agent that acts in real environments.
Investigate code, review potential vulnerabilities, and develop patches in authorized security workflows.
Bring your tasks, files, and tools into a hosted agent workspace. Explore the models currently available for your account.
Explore models in MyClaw